

OmniHuman 2.0 in Doppelshot
OmniHuman 2.0 is ByteDance's audio-driven human video model: one photo, one voice track, and the person speaks or sings with matching lips, face and hands. Doppelshot runs it on the Say it and Sing cards, with a direction you can give it (what the person does while speaking).
What it is
- Audio-driven: the lips, the breath and the gestures follow the voice track.
- Takes a direction in words ("looks up, then smiles at the end"), unlike most talking engines.
- Full body or close-up, from one photo.
What Doppelshot makes with it
- Say it: your script, a library voice or your cloned voice, 10 credits per 10 seconds.
- Sing: your photo sings a jingle or your own song.
- Longer scripts: 20 and 30 seconds at the same rate.
Engines and prices
| Engine | Kind | Price | Cards |
|---|---|---|---|
| OmniHuman 2.0Recommended | Talking video | 10 credits | Say it, Three emotions |
Checked against the catalog on 2026-10-21.
Cards that run on it
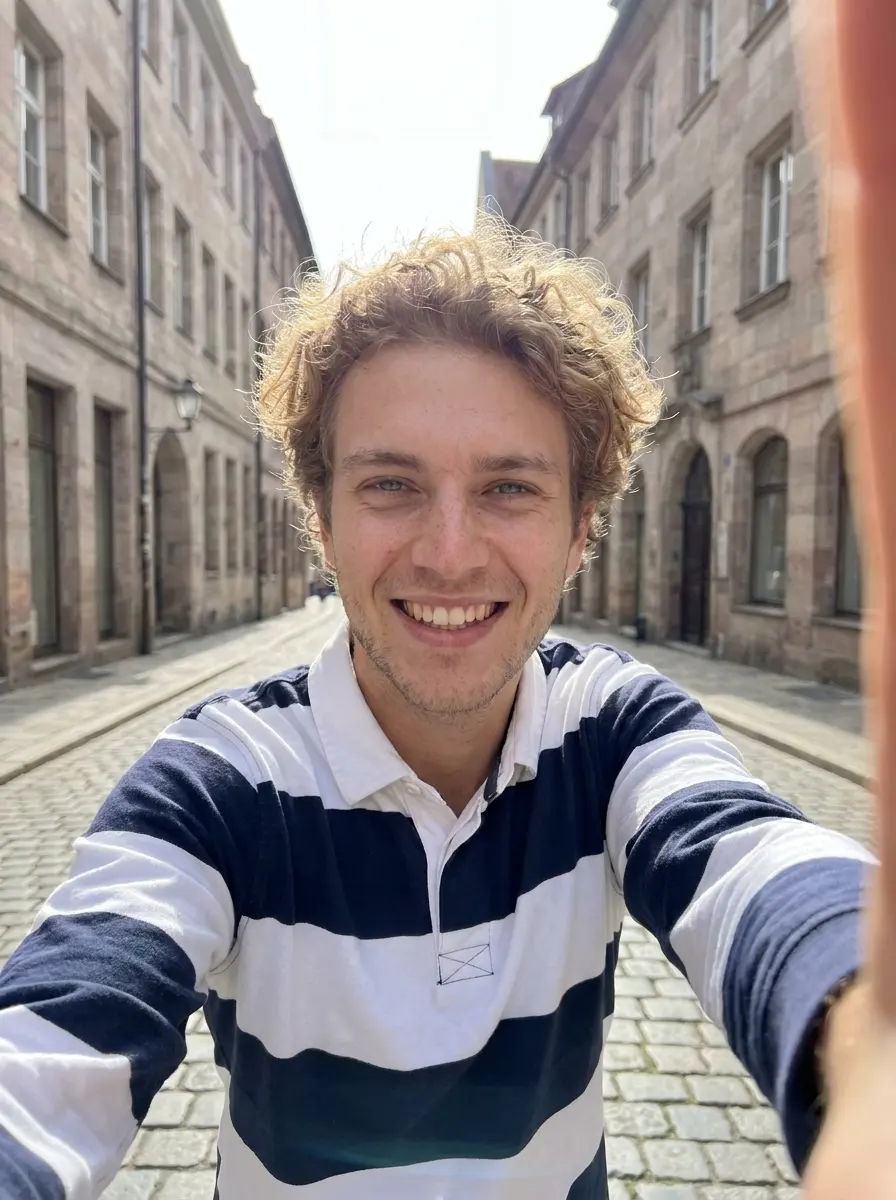
Open a card, drop your selfie, and pick this engine in the Studio when it is not the default.
Questions
OmniHuman or LTX for a talking video?
OmniHuman for expressive, gestural speech and for singing; LTX when you want a cinematic frame around the person. Both lip-sync.
Which voice?
Any of about 30 library voices, or a clone of your own voice made in the app. Leave the voice on Auto and it follows the person in the photo.
OmniHuman 2.0 or 1.5?
OmniHuman 2.0 (October 2026) replaced 1.5 on the cards: it takes a direction in words, speech from 4 seconds to 5 minutes, and costs 10 credits per 10 seconds instead of 20. Doppelshot runs it directly on BytePlus, ByteDance's cloud.